AI & infrastructure
A personal Ubuntu server with an RTX 3050 GPU and Ollama for local language-model development. Tailscale provides private remote connectivity, with hardened SSH access.
Loading image…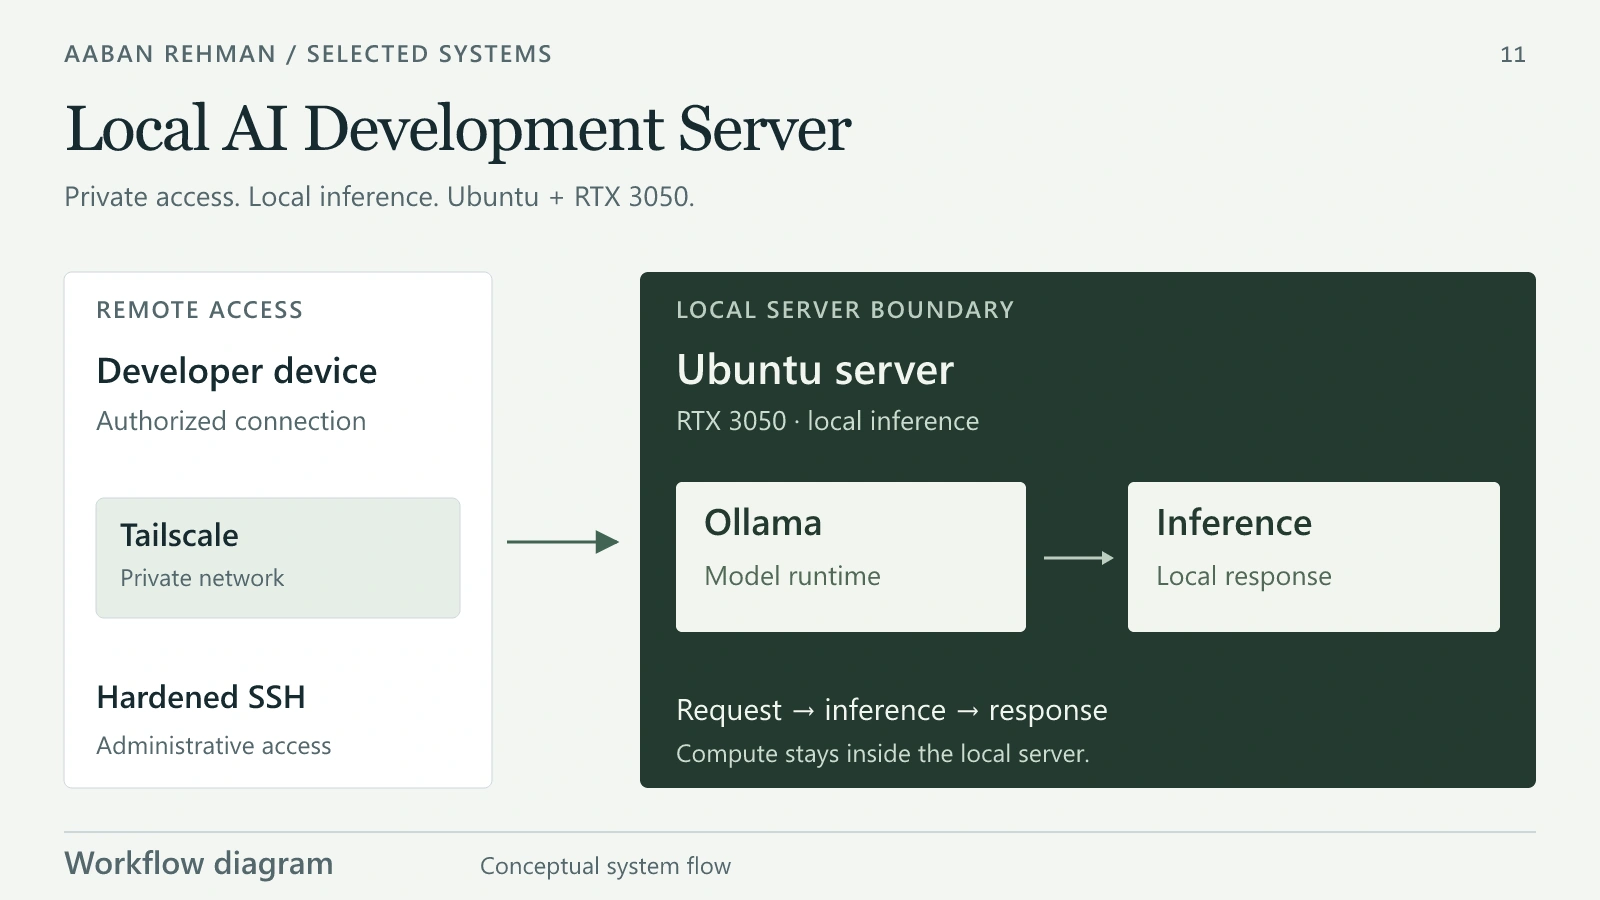
Conceptual workflow diagram showing private remote access and local Ollama inference on an Ubuntu server
The problem
Local model experimentation needs usable GPU hardware and convenient remote access while keeping the server's access controlled.
The approach
Run models locally through Ollama on the Ubuntu GPU server and use Tailscale for private connectivity. Harden SSH and expose access selectively through the private network.
- Local language models with Ollama
- GPU-equipped Ubuntu environment
- Private connectivity through Tailscale
- Hardened SSH access
My contribution
Personal infrastructure setup & administration
Technology
Ubuntu Linux, NVIDIA RTX 3050, Ollama, Tailscale, SSH
Discuss a similar workflow